Serve mode¶
swarmkit serve starts a persistent HTTP server for production workloads.
Quick start¶
Endpoints¶
The complete list — every route, generated from the server's OpenAPI document — is the HTTP API reference. Below are the ones a caller integrates with and what they take.
Jobs¶
| Method | Path | Description |
|---|---|---|
POST |
/run/{topology} |
Submit a topology run (async); returns a job id. Body: input, optional attachments, correlation_id, labels, supersedes |
GET |
/jobs/{id} |
Poll job status (in-memory, then the durable store) |
GET |
/jobs/{id}/stream |
The job's events as server-sent events |
GET |
/jobs/{id}/diff |
The unified diff a harness run produced, per agent |
POST |
/jobs/{id}/resume |
Continue a run parked on a human gate (deferred) |
POST |
/jobs/{id}/stop |
Ask a running job to stop at its next agent boundary |
GET |
/jobs/history |
Every recorded run, newest first (survives restart) |
Attachments¶
A caller that already holds a file — a snapshot, an uploaded photo — passes it beside the input instead of making an agent go and fetch it:
POST /run/describe-scene
{
  "input": "What is at the gate?",
  "attachments": [
    { "path": "snapshots/gate-1732.jpg" }
  ]
}
| Field | ||
|---|---|---|
path |
workspace-relative | exactly one of path / data |
data |
base64 | for a caller holding bytes rather than a file |
name |
optional | display/filename; derived from path when absent |
handling |
preprocess (default) or native |
intent for non-image types; inert today |
There is no type field. The media type is read from the file's content — sending one is a
422, because a caller's claim about bytes that are about to be forwarded to a model is not evidence.
url and stream sources are refused for the same reason and a related one: the runtime does not
fetch caller-supplied addresses, and an attachment is re-read on every turn of a tool loop, so it
has to be re-readable.
Attachments reach the entry agent's first message and no downstream node. An agent that wants a file it was not handed asks for one through a skill.
A bad path is a 422 on this request, not a job that fails a moment later — so a job id means the
file was readable. Only images are carried today (image/png, image/jpeg, image/gif,
image/webp); anything else is refused by name. Per-attachment ceiling is 20 MB
(SWARMKIT_ATTACHMENT_MAX_BYTES).
Every attachment is written to the audit log as a run.attachments event carrying name, media type,
size, SHA-256 and source path — never the bytes. The digest is what makes the reference
checkable later; storing content would put arbitrary material into a log meant to stay readable.
The CLI equivalent is swarmkit run <ws> <topology> --attach <path> (repeatable).
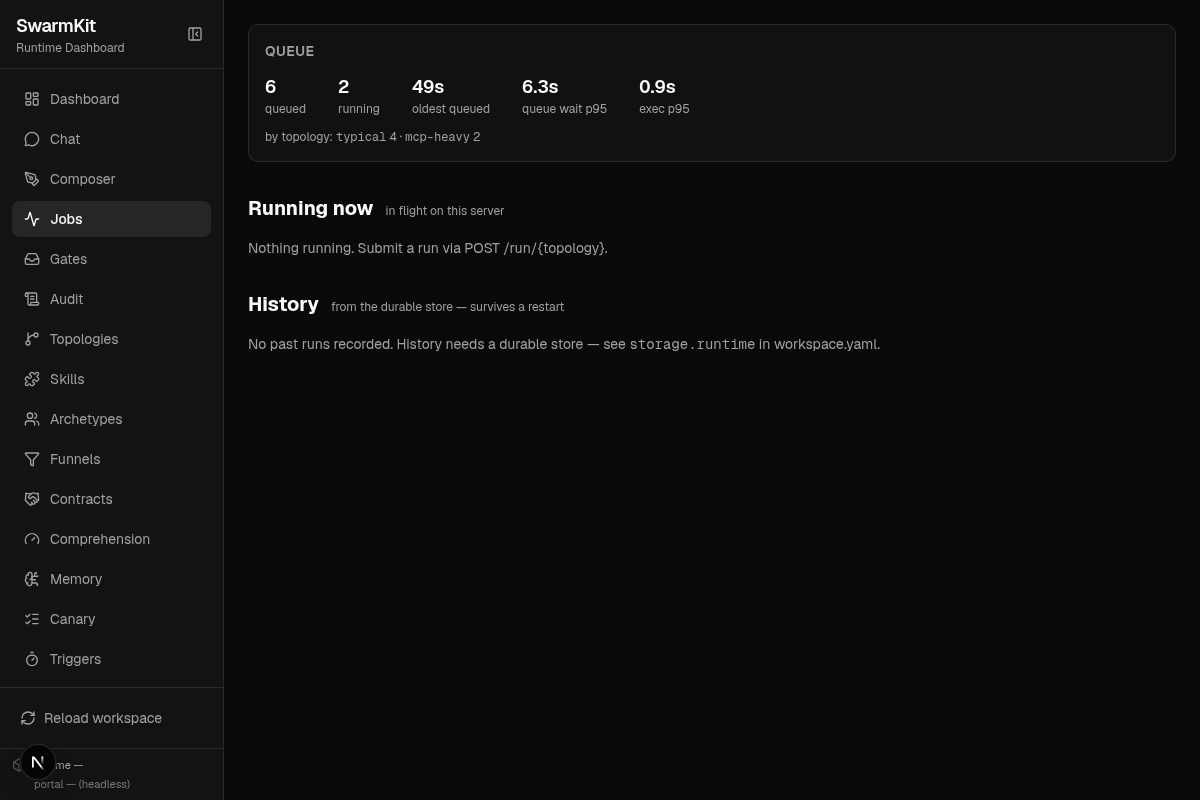
The portal's Jobs view shows live queue health from GET /queue/stats — backlog depth,
oldest-unclaimed age, queue-wait and execution p95, and depth by topology (queue-observability.md):
Conversations¶
| Method | Path | Description |
|---|---|---|
POST |
/conversations |
Create a new conversation |
GET |
/conversations |
List conversations |
GET |
/conversations/{id} |
Load full conversation history |
POST |
/conversations/{id}/messages |
Send message (SSE streaming) |
CRUD (topologies, skills, archetypes)¶
| Method | Path | Description |
|---|---|---|
GET |
/api/topologies |
List topologies |
GET |
/api/topologies/{id} |
Get topology details |
GET |
/api/topologies/{id}/yaml |
Get raw YAML |
PUT |
/api/topologies/{id} |
Replace the YAML (validated before it is written) |
POST |
/api/topologies |
Create new topology |
DELETE |
/api/topologies/{id} |
Delete topology |
Same pattern for /api/skills and /api/archetypes.
Usage tracking¶
| Method | Path | Description |
|---|---|---|
GET |
/usage |
Global token usage summary |
GET |
/usage/{job_id} |
Per-job usage breakdown |
MCP endpoint¶
| Method | Path | Description |
|---|---|---|
POST |
/mcp/ |
Streamable HTTP MCP endpoint — every topology as a run_<name> tool, behind the same auth (Level 11) |
Each topology becomes an MCP tool. External agents can call your swarm topologies via standard MCP protocol.
A2A endpoint¶
Off by default; server.a2a.enabled: true turns it on (no restart — a reload is enough).
| Method | Path | Description |
|---|---|---|
GET |
/.well-known/agent-card.json |
The Agent Card: one A2A skill per topology; public (no auth) |
GET |
/a2a/{topology}/card |
The same card narrowed to one topology |
POST |
/a2a |
JSON-RPC 2.0: message/send, message/stream, tasks/get, tasks/list, tasks/cancel, tasks/subscribe; the message's metadata.skill names the topology |
POST |
/a2a/{topology} |
The same, bound to one topology (the card's per-skill url) |
A2A is a transport onto jobs, not a second execution path: message/send is POST /run/{topology}
(contextId → correlation_id, file parts → attachments), tasks/get is GET /jobs/{id}, tasks/cancel
is POST /jobs/{id}/stop, and the streaming methods re-emit GET /jobs/{id}/stream as A2A
status/artifact events. The task id is the job id; the run carries source: a2a and appears in
the portal's jobs page like any other. Task states map from job status: pending→submitted,
running→working, deferred→input-required, completed, failed, stopped→canceled.
A run parked on a human gate reports input-required with the gate's URL in the status message, but
the A2A caller cannot supply that input: approval scopes are un-grantable to agents, so a
follow-up message/send on the task is refused with UnsupportedOperationError and the gate URL. A
person resolves it through the review queue; a subscribed client sees the task go working again.
Push notifications, gRPC and card signing are not implemented (-32003 / -32004). Streaming
methods need Accept: text/event-stream. Full mapping: design/details/a2a-interop.md.
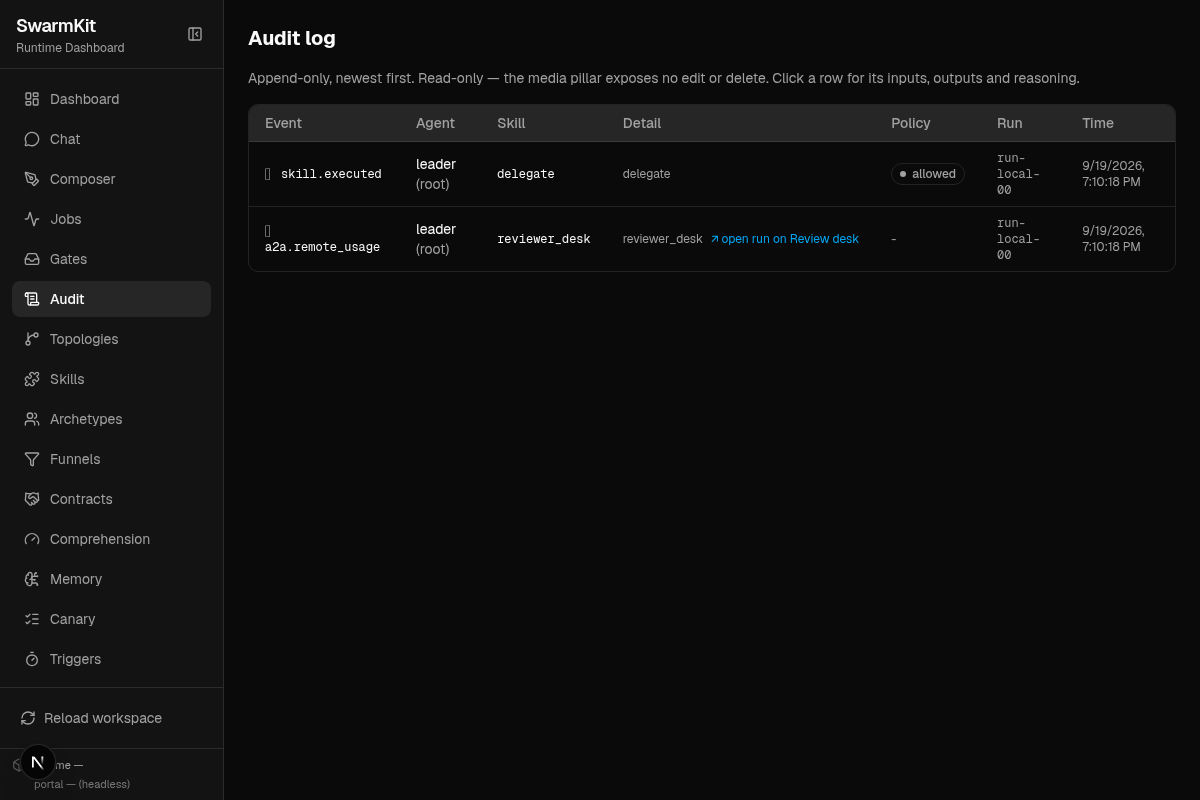
When both ends are SwarmKit (a2a-federation.md), a call returns the callee's run id, token/cost
usage and an observability pointer, and the caller forwards its remaining budget. The portal's
Audit view turns the returned run id into a link — an a2a.remote_usage event opens the callee
instance's own job detail, so a federated call no longer dead-ends at "called a remote agent":
Webhooks¶
| Method | Path | Description |
|---|---|---|
POST |
/hooks/{topology_name} |
Fire a webhook trigger: an HMAC-signed request starts the named topology |
Webhook signatures are validated with HMAC-SHA256 when secret is configured on the trigger.
Canary¶
| Method | Path | Description |
|---|---|---|
GET |
/canary |
List canary routes and metrics |
POST |
/canary/{topology}/promote |
Promote canary version |
POST |
/canary/{topology}/rollback |
Rollback canary version |
Authentication¶
Configure in workspace.yaml:
server:
  auth:
    provider: jwt
    jwks_url: https://your-idp/.well-known/jwks.json
    audience: swarmkit
    issuer: https://your-idp/
Available providers:
| Provider | Description |
|---|---|
none |
No authentication (default) |
api_key |
Bearer keys declared in workspace.yaml — server.auth.config.keys[], each a key_ref: env:<VAR> (a reference, never the literal), a client_id and a tier (read / run / admin) or explicit scopes. See the serve auth guide |
jwt |
JWT with JWKS auto-discovery |
Access audit¶
Every authenticated mutating call (serve:run / serve:admin tier, including 403s) is recorded in
the serve_access table: client id, auth provider, method, path, required action, status and time.
This is the transport access log. Run audit events (what agents did, gates and decisions) are
separate and use their own write-through journal.
--access-audit (env SWARMKIT_ACCESS_AUDIT) chooses how the rows are written:
| Mode | How | On kill -9 |
Cost |
|---|---|---|---|
batched (default) |
buffered in memory, written in one transaction every 250 ms off the request path; flushed on clean shutdown; a failed write is retried at the next flush | loses at most the last ~250 ms of rows, which are not recovered on restart | none on the request path |
sync |
written before the response, one transaction per mutating request | nothing acknowledged is lost | one database write on the event loop per mutating request |
Choose sync when a requirement says every API call must be durably recorded before it is
acknowledged. Each row's time is when the call completed in either mode. With several serve
processes in batched mode, row ids can be up to one batch window out of time order. See
design/details/api-tier-submit-path.md and load-and-scale.md Run 8.
$ swarmkit serve ./ws --access-audit sync
...
access audit: sync — each row written before its response.
Production profile (fail-closed preflight)¶
swarmkit serve --profile production refuses to start unless the deployment is safe to expose,
listing every gap at once instead of running permissively. It is a deployment-time assertion — it
does not change request handling (governance is already deny-by-default), it checks that you
configured the safe thing. --profile standard (the default) is the unchanged laptop behaviour.
The preflight requires all of:
| Requirement | Why |
|---|---|
Auth is not none/anonymous |
production does not serve anonymous, on any bind |
--insecure is not set |
the escape hatch is incompatible with the profile |
SWARMKIT_OAUTH_KEY is set |
else the token-encryption key regenerates on restart and silently invalidates stored tokens |
Every mcp_servers entry is sandboxed: true |
a tool process must not run unisolated on the host (design §8.8) |
No wildcard --cors-origin * |
exact origins only |
$ swarmkit serve ./ws --profile production
--profile production refuses to start: the deployment is not fail-closed.
  1. auth provider is 'none' — configure server.auth (api_key or jwt); production does not serve anonymous, on any bind
  2. SWARMKIT_OAUTH_KEY is not set — the OAuth token-encryption key would regenerate on restart and silently invalidate every stored token; set a persistent key
  3. MCP server 'files' is not sandboxed — set `sandboxed: true` so the tool process runs isolated (design §8.8)
Fix these, or run without --profile production for the permissive default.
The existing default-secure refusal (an unauthenticated non-loopback bind) still runs regardless of
profile; production adds to it. create_app(profile="production") carries the preflight, so an
embedder inherits it too.
Server configuration¶
server:
  host: "0.0.0.0"
  port: 8000
  jobs:
    max_concurrent: 5
    timeout_seconds: 300
  mcp:
    enabled: true
  a2a:
    enabled: false          # publish the Agent Card + serve /a2a
    identity:               # optional; what the card says about this instance
      name: Review desk
      description: Code review and triage swarms, human-gated.
      url: https://swarm.example.com   # set behind a proxy; default is the request's host
      organization: Example Org
/capabilities reports features.a2a so a fleet can see which instances publish a card.
Triggers¶
Cron and webhook triggers are defined in triggers/*.yaml:
apiVersion: swarmkit/v1
kind: Trigger
metadata:
  id: nightly-review
  name: Nightly Code Review
type: cron
schedule: "0 2 * * *"
topology: code-review
input: "Review all PRs opened today"
apiVersion: swarmkit/v1
kind: Trigger
metadata:
  id: pr-webhook
  name: PR Webhook
type: webhook
topology: code-review
secret: ${WEBHOOK_SECRET}